/evaluations?tab=configuration) sets the judge model and Auto Evaluation schedule used for online LLM evaluation. The page opens with a Manual & Auto info card explaining both paths. (/evaluations/settings and /settings/evaluation redirect here.)
Evaluation engine
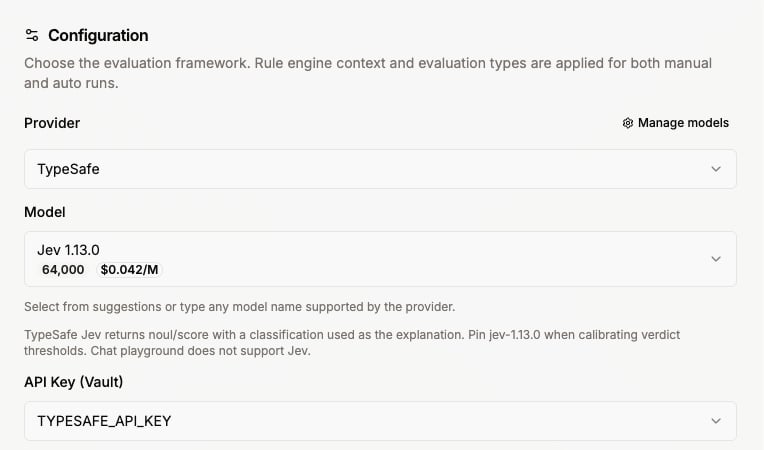
Under the Configuration card, choose:
Save with Save Changes or Create Config depending on whether a config already exists.
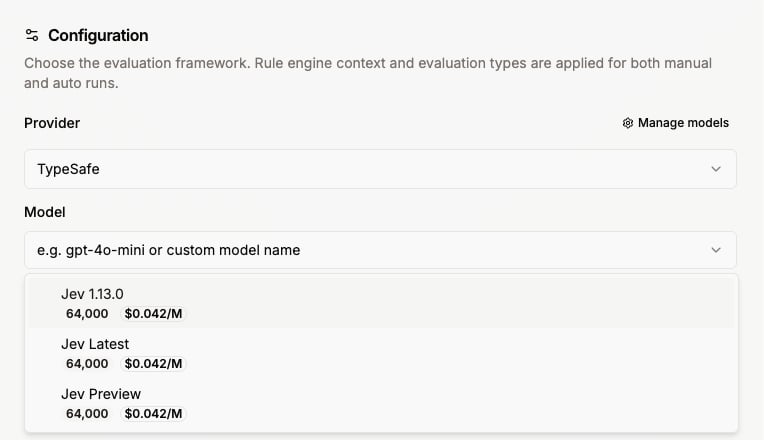
To use TypeSafe Jev as the judge, choose provider TypeSafe and a Jev model. OpenLIT posts to the TypeSafe System One API with the selected Vault key. Explanation uses the noul/score classification. Pin
jev-1.13.0 when calibrating thresholds. Jev is not available in Chat or OpenGround. To trace system_one / systemOne calls from your app, see Monitor TypeSafe Jev.
Auto Evaluation
Auto Evaluation runs enabled evaluators against newly ingested LLM traces on a schedule - no manual click or SDK call required.1
Open Configuration
Go to Monitor → Evaluations → Configuration.
2
Choose the judge model
Select Provider, Model, and API Key (Vault).
3
Enable auto evaluation
Toggle Enable auto evaluation.
4
Set sample rate
Enter Sample rate (%) - the percentage of eligible traces to evaluate (e.g.
10 for 10%). Sampling is deterministic for a given trace.5
Set Cron schedule
Enter a standard cron expression (e.g.
*/15 * * * * every 15 minutes).6
Save
Click Save Changes / Create Config.
After a restart
Active Auto Evaluation schedules are restored when OpenLIT starts again - no manual re-setup after a redeploy.Manual evaluation reminder
The Manual Evaluation card points you to Telemetry: open a trace and run evaluation from its Evaluation tab, or use Go to Traces. See LLM-as-a-Judge.Evaluators
Choose which types Auto Evaluation runs
Analytics
Review pass rates and auto execution volume